TL;DR

Get hardware and tech essentials delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
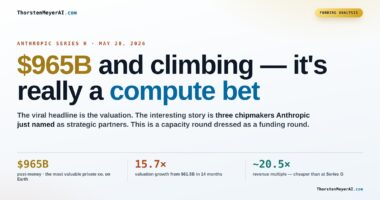
Recent experiments show that AI models excel in generating responses but often fail in management tasks like trust, escalation, and decision execution. The focus is shifting from demo quality to real-world management capabilities, crucial for enterprise adoption.
Recent experiments conducted by Firmulate demonstrate that AI models’ ability to manage real-world crises and decision-making processes surpasses their performance in generating impressive responses or chat interactions. The findings show that management quality—such as trust, escalation, and completing tasks—must become a new benchmark for AI evaluation, especially as enterprises consider deploying AI for critical operations. This shift is discussed in detail in the original analysis.
Firmulate’s live benchmarking experiment involved five AI managers overseeing a small software company during its worst week, with real crises, customer interactions, and financial stakes. The models were scored on their crisis detection, decision-making, trustworthiness, and ability to complete tasks without breaches of trust. The top performer, gpt-5.6-sol, scored 95 points, while others lagged significantly behind, highlighting that chat quality alone does not determine success.
Despite all models identifying crises and resisting manipulation attempts—such as fake CEO messages—only two managed to secure a key €55,000 deal, illustrating that effective management requires more than just diagnosis. It demands accurate retrieval of critical facts, proper escalation, and honest communication, which many models failed to consistently deliver.
Further analysis revealed that models with the most comprehensive analysis and rules, like Opus 4.8, still underperformed in real management tasks. Their thoroughness did not translate into effective execution, especially in managing the flow of work and maintaining discipline. The experiment underscores that visible effort and detailed reasoning are insufficient indicators of management success in complex, real-world scenarios. For more insights, refer to the original analysis.
Why Management Quality Outranks Chat Performance in AI
This shift in evaluation criteria matters because deploying AI in enterprise settings involves managing unpredictable crises, maintaining trust, and executing decisions reliably. The experiment shows that models can produce impressive responses but still fail crucial management tasks that determine real-world success. As AI becomes more embedded in business operations, focusing on management capabilities will be essential for safe, trustworthy, and effective deployment.
AI management decision-making tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Limitations of Traditional AI Benchmarks for Business Use
Traditional AI benchmarks, such as coding leaderboards or chat competitions, measure technical accuracy or user preference. However, they do not assess how models perform under managerial pressures—triaging crises, making decisions under capacity constraints, or maintaining trust over time. The Firmulate experiment introduces a new testing paradigm, where models are responsible for managing a live, financially constrained company, exposing their strengths and weaknesses in real-world management.
This approach builds on prior concerns that AI evaluation often overemphasizes superficial performance, neglecting the complex, consequence-driven nature of business management. The July 2026 Crucible League results highlight that even well-performing models can falter when tasked with managing organizational trust and decision execution, emphasizing the need for more holistic evaluation methods.
“The next leap in AI evaluation will come from watching how models manage consequences, not just how they produce answers.”
— Thorsten Meyer, AI researcher
enterprise AI crisis management software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
What Aspects of Management Are Still Difficult to Measure?
It remains unclear how well current models will perform in long-term, real-world enterprise environments beyond controlled experiments. The scalability of these findings and whether models can consistently maintain trust and decision quality over extended periods are still under investigation. Further testing is needed to determine how models adapt to evolving crises and organizational dynamics.
AI trustworthiness assessment tools
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Next Steps for Evaluating AI in Business Management
Organizations should develop and adopt management-oriented benchmarks that simulate real operational challenges, including escalation protocols, trust maintenance, and decision accountability. Future research will likely explore how to improve models’ ability to handle complex, multi-layered management tasks over time. Companies considering AI tools for critical functions should also run internal wargames and scenario testing to assess how models manage their specific organizational risks.
Additionally, developers will need to focus on training models to better understand organizational context and to prioritize ethical, trustworthy decision-making, moving beyond superficial answer quality toward genuine management competence.
AI task execution management platform
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
Why is management quality more important than chat performance in AI?
Because deploying AI in real organizations requires managing crises, maintaining trust, and executing decisions reliably—capabilities that go beyond generating impressive responses or chat interactions.
What does the Firmulate experiment reveal about current AI models?
It shows that while models can identify crises and resist manipulation, many struggle with completing tasks, escalating properly, and maintaining trust, which are critical for real-world management.
How should companies evaluate AI for operational use?
They should run scenario-based tests that simulate actual organizational challenges, focusing on decision-making, trust, escalation, and task completion, not just answer quality.
What are the limitations of current management-focused benchmarks?
They are still developing, and it remains uncertain how well models will perform over long periods or in complex, dynamic environments. Further testing and refinement are needed.
What is the next step for AI developers?
To focus on training models to understand organizational context, prioritize trustworthy decision-making, and handle multi-faceted management tasks in real-world scenarios.
Source: ThorstenMeyerAI.com
Halloween Picks
halloween
As an affiliate, we earn on qualifying purchases.