TL;DR

Get hardware and tech essentials delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
A user successfully configured an RTX 5080 and RTX 3090 together, reaching over 80 tokens/sec on Qwen 3.6 27B Q8. This demonstrates potential for high-performance local AI setups. Details on the setup and performance are confirmed; broader applicability remains to be tested.
A user has successfully configured an RTX 5080 and RTX 3090 in a single system, achieving over 80 tokens per second on Qwen 3.6 27B Q8, demonstrating significant performance gains in local AI inference.
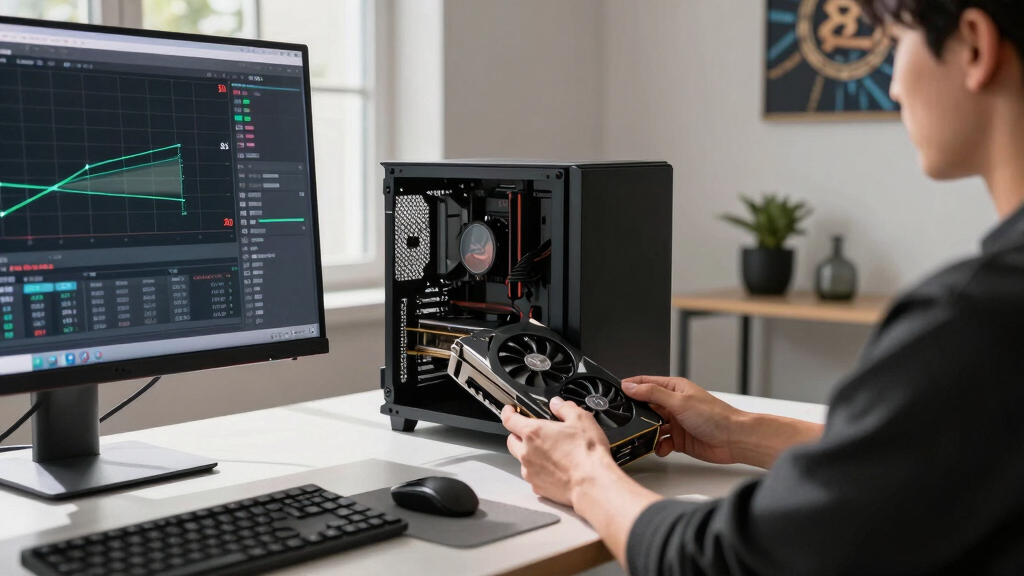
The setup involves a custom hardware configuration with an Asus Prime X570-Pro motherboard, PCIe 4 riser, and specific BIOS and driver adjustments to enable dual-GPU operation. The user reports running a quantized Qwen 3.6 model at q8 with a context size of 230,000 tokens, reaching inference speeds of 80 to 90 tokens per second.
This performance was achieved by enabling specific BIOS settings such as Above 4G Decoding and ReSize BAR Support, and installing patched NVIDIA drivers compatible with different GPU models. The user utilized llama.cpp with particular build flags supporting both Ampere and Blackwell architectures, optimizing VRAM usage across the two cards.
Implications for Local AI Hardware Performance
This achievement underscores the potential for high-performance AI inference using consumer-grade GPUs in multi-GPU setups. It could influence future hardware configurations for AI researchers and enthusiasts seeking to run large language models locally, reducing dependency on cloud services.
While confirmed for this specific configuration, broader adoption and scalability depend on further testing with different models and hardware combinations.
As an affiliate, we earn on qualifying purchases.
Advances in Multi-GPU AI Inference Setups
Over the past year, enthusiasts have experimented with combining high-end GPUs like the RTX 5080 and RTX 3090 to push local AI inference speeds. Previous benchmarks with single GPUs topped at around 50-60 tokens/sec on similar models. The user’s recent report suggests that with proper BIOS and driver configurations, multi-GPU setups can significantly boost performance, reaching over 80 tokens/sec.
This development aligns with ongoing efforts to optimize hardware for large language model inference outside data centers, leveraging consumer hardware and customized software configurations.
“Achieving over 80 tokens/sec on Qwen 3.6 27B Q8 with this dual-GPU setup demonstrates promising performance gains for local AI inference.”
— the user who conducted the setup
As an affiliate, we earn on qualifying purchases.
Scope and Generalizability of Performance Gains
It is not yet clear how broadly this performance improvement can be replicated across different hardware configurations, models, or workloads. The setup involves specific BIOS and driver modifications that may not be universally applicable or stable for all users.
Further testing is needed to determine if similar speeds can be achieved with other models or in different system configurations, and whether long-term stability is maintained under sustained workloads.
As an affiliate, we earn on qualifying purchases.
Next Steps for Multi-GPU AI Performance Testing
Additional users and researchers will likely attempt similar configurations to validate and expand upon these results. Future work may include testing with different models, refining BIOS and driver settings, and exploring scalability with more GPUs.
Hardware manufacturers may also consider optimizing BIOS and driver support for multi-GPU AI workloads based on these emerging benchmarks.
motherboard for multi-GPU gaming and AI
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
Key Questions
Can I replicate this setup with my GPUs?
Replicating this setup requires specific BIOS adjustments, driver patches, and hardware compatibility. It is recommended only for advanced users familiar with BIOS and driver configurations.
Does this performance apply to all models of Qwen 3.6?
This performance is confirmed for the specific quantized Qwen 3.6 27B Q8 model used by the user. Results may vary with different models or quantization settings.
Is this setup stable for long-term use?
Stability over extended periods has not been confirmed. Users should proceed cautiously and perform thorough testing before deploying in critical environments.
Will future GPU releases improve these speeds?
Potentially, future GPU architectures and driver improvements could further enhance multi-GPU AI inference performance.
Source: Hacker News
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.